Replying to @garjoh_canuck and @adambroach, @rochemathieu, @johnwilander
DNT by default is what matches user expectations. What is unsustainable in the legacy advertising model is that it is hostile to user preferences while claiming to deliver more relevant ads that users want. It can't work both ways.
Replying to @rochemathieu and @garjoh_canuck, @adambroach, @johnwilander
There is no evidence that the choice is between privacy and paying. That's just where things got stuck, advantaging specific players who are neither users nor publishers.
Replying to @rochemathieu and @johnwilander, @garjoh_canuck, @adambroach
Bid listening is how programmatic is expected to work now. Privacy in the browser solves that problem well.
Also consent without fraud is *exactly* DNT by default!
Replying to @rochemathieu and @adambroach, @johnwilander, @garjoh_canuck
That argument can hold if the data is actually processed by the first party or by processors it can make reasonable representation for. That is completely different from the world we are in.
Replying to @rochemathieu and @adambroach, @johnwilander, @garjoh_canuck
What you describe is actually a lot closer to what ITP enables, and is exactly what DNT was designed to enable. There is nothing wrong with using personal data, but it needs to happen in a way that can be explained to the user.
Replying to @rochemathieu and @adambroach, @johnwilander, @garjoh_canuck
The current system makes it impossible for publishers to tell their users what is happening. You can't ever have the conversation you describe on those terms!
Replying to @garjoh_canuck and @rochemathieu, @adambroach, @johnwilander
If users want it so much why not switch to an opt in model? The power of defaults is well documented, trying to argue low opt outs without reference to that fact is dishonest.
Replying to @rochemathieu and @adambroach, @johnwilander, @garjoh_canuck
The IAB has been giving the "more transparent" talk for a solid decade now with close to nothing to show for it. Nothing is unilateral here, and "all" tracking is not at play, only hidden third party. It's not that dramatic!
Replying to @rochemathieu and @marionpdaly, @johnwilander, @adambroach, @garjoh_canuck
Stakeholders were called to the table for DNT. They worked their best to derail the process. The door is still open if they want to act in good faith now but no one can complain about anything happening unilaterally. The web community spent enormous energy on this.
Replying to @scottmichaud and @adambroach, @garjoh_canuck, @rochemathieu, @johnwilander
That's a common misunderstanding. DNT was not created to protect against malicious actors, but to tie into the legal infrastructure. By your definition, contracts are also useless because people can just ignore them.
Replying to @scottmichaud and @adambroach, @garjoh_canuck, @rochemathieu, @johnwilander
A browser works first and foremost for its users, that's documented as the Priority of Constituencies. If Microsoft had reason to believe that its users favoured DNT by default it is their responsibility to act on that.
The whole point of having a DNT API was meant to be that the browser could have a default but the website could ask for exemptions from that default, no matter what it is.
I think what I'm missing is the following phases? It's a nice addition, but so long as it requires manual intervention I don't see the value. But I'm psyched if there's something cool from this down the line!
Replying to @null and @SimonDeDeo, @MastodonProject, @urbit
Opera tried the "browser for the server side" thing but it tanked pretty fast (you can certainly still find copies). I wonder how much of the vision @BeakerBrowser enables.
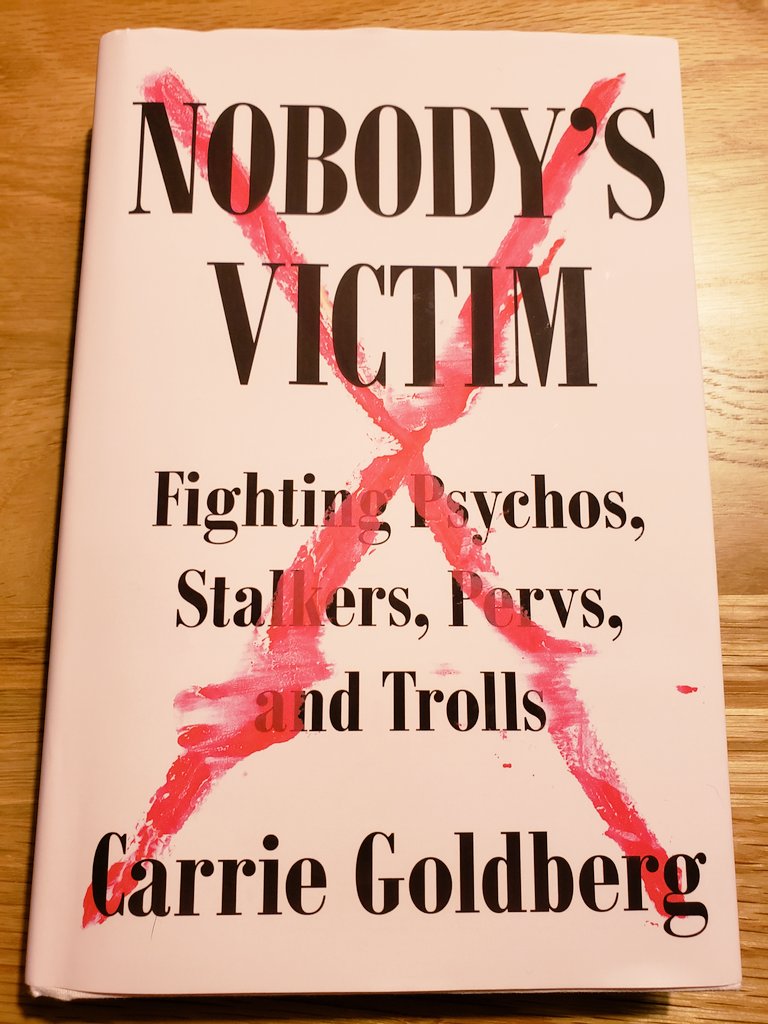
"Nobody's Victim", by @cagoldberglaw.
If you're in any kind of doubt that we've seriously fucked up building the Internet and its supporting policies then I would really like you to read this book.
I should warn you that much of it is heart-rending. Sobbing or rage may ensue - it certainly did for me.
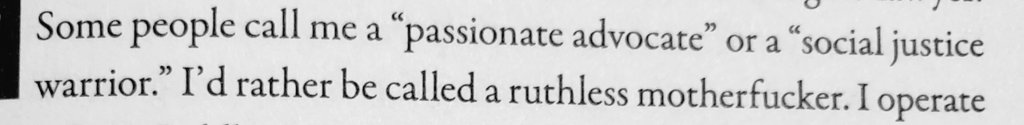
Yet it is written with a fiery warpath spirit that makes it clear there is a way forward worth fighting for. Taking from her first paragraph, I'd have that as my epitaph:
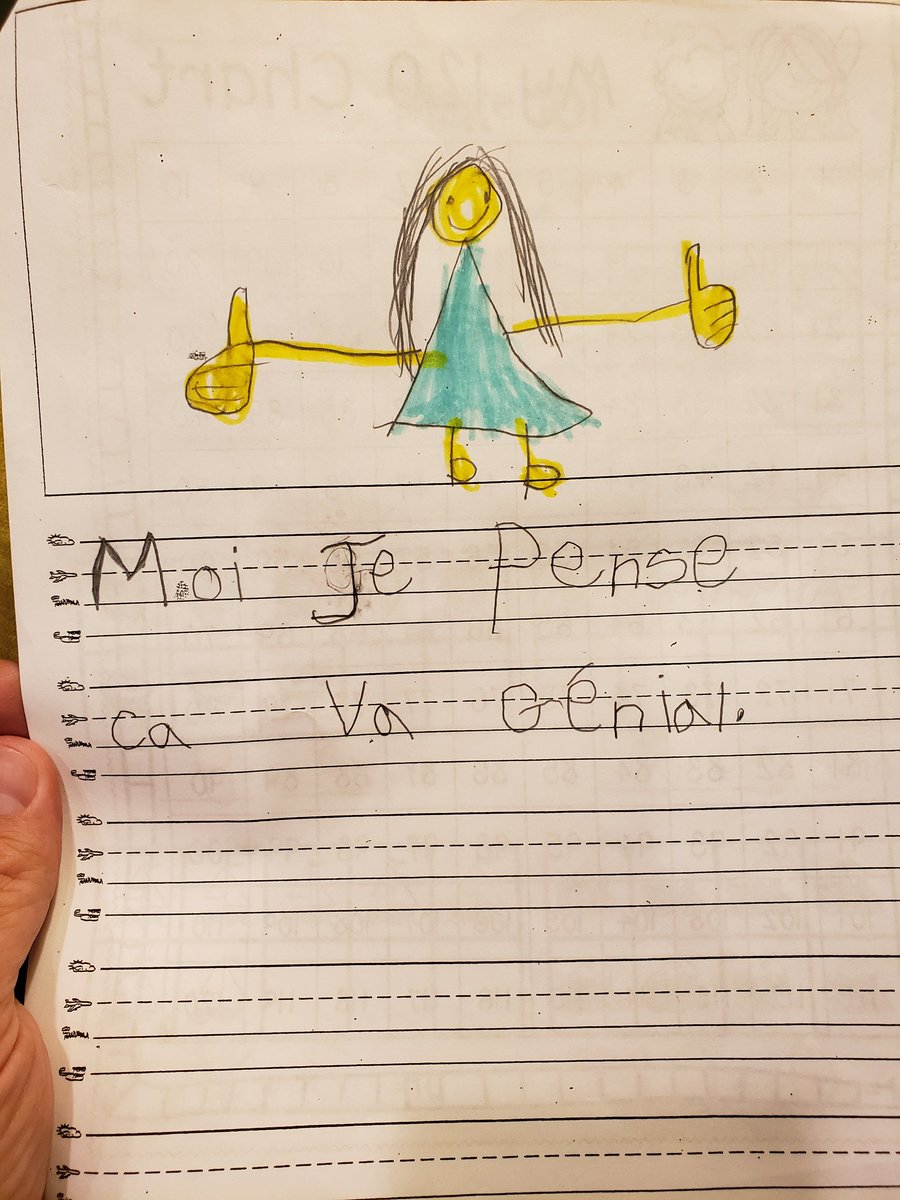
Yes, that's the sort of thing I had in mind. I was mostly wondering if I should go with one of those sites that offer to find pen pals (I have no idea if they're good!) or if someone on this site might know the right kid!
I *think* they see it as a bargaining chip because it’s the option that hurts the EU the most. But concluding from that that it’ll be enough to make the EU blink is a gross miscalculation.
To some degree you could make that comparison, it’s not very different from when two companies need to renew a contract but disagree on terms — not reaching agreement could lead to a discontinuation of service harmful to both.
But what’s at stake for the EU is existential survival: if they yield then they risk facing other exits. So they’ll take the no-deal harm over risking disintegration, even if it really is painful. Not getting that is leading the UK to overplay a poor hand.
A great set of issues in this article, from whether Big Tech can learn from Microsoft's mistakes to how to build a worldwide regulatory environment for tech.
theatlantic.com/ideas/archive/…
If you have a massive tracking infrastructure and reams of personal data, it’s in your interest to push the industry in the direction of thinking that’s the only, or at least the most effective, way of running ads.
Put differently, there’s a killzone in ad innovation around solutions that don’t involve personal data. Google’s position also allows them to impose their legal interpretation on others, as happened with the GDPR. So there is a link.
But in general I agree that looking at any one aspect of Alphabet on its own is unlikely to spot the forest. They need to look at it as a conglomerate that self-deals and hedges against itself to always win — that’s the anticompetitive system.
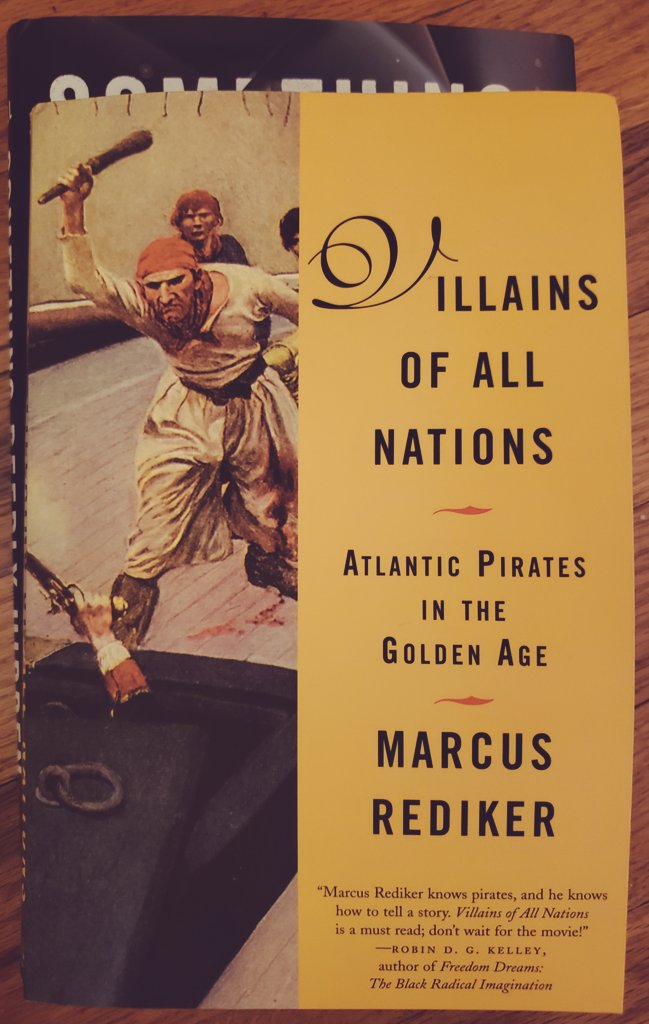
Wow, I so want. Goodreads is totally useless; the only social network I’ve found usable to talk about books is on here and let’s just say it’s not really built for it.
Just one sentence, but read the whole @matthewstoller: "Google and Facebook both compete with publishers for ad revenue and force those publishers to hand over data about their readers and subscribers, data which is the main input that advertisers want." amp.theguardian.com/commentisfree/…
If you genuinely want to get this back up, happy to chat in a venue with longer messages.
Starting with identity is probably a nonstarter but identity can be part of the solution, Don and I have discussed this before.
Chrome muddies this but the browser's job is literally to represent the user, that's why it's called a "user agent". Putting this with the browser would make sense.
DNT by default and/or a ban on all 3P tracking plus an opt-in browser controlled identity might work.
Exactly, and this could work with governance to ensure it adheres to a high standard of opt-in (not TCF), is mindful of vulnerable users, allows for multiple IDs, only works with auditable data chains, etc.
Replying to @larry_irving and @dmarti, @kickstand, @DSepDC
Yeah, that's definitely part of the plan. The point here is that privacy is about appropriate flow of information. We will only have a sustainable data economy if it becomes appropriate for all, and that can't mean covert tracking by default.
This is what the alt-right looks like when it doesn't have the power of Google, Facebook, or Twitter to back it. I could see more of this. t.co/tCt8dwOSNZ
Framasoft has framagenda.org — I haven’t tried any of their offering in a while. It then works with any DAV client (which may or may not be a scary proposition).
Purely as a signalling mechanism, yes, though it needs some solid governance and enforcement backed by stronger processing requirements (ie. it needs to be industrialised as a standard). But no need to throw the ideas away indeed.
Replying to @Forsheit and @jason_kint, @TheTakeaway
It’s worth noting that the fact that the current advertising ecosystem does finance *some* volume of journalism should not be taken for evidence that it does so effectively, fairly, or competitively, in a manner advantageous to the press.
Replying to @Forsheit and @jason_kint, @TheTakeaway
I don’t think it’s about imagining a better world; it’s hard to imagine a world in which the press is being wiped out faster than it already is. At the current pace most of those publishers are dead if we don’t change tack.
Replying to @Forsheit and @jason_kint, @TheTakeaway
I also don’t think it’s about ads vs subs. We need a regulated ad market if we don’t want behemoth intermediaries to steamroll smaller players. I agree that the CCPA is problematic there in that it doesn’t do enough.
Replying to @lukemulks and @johnnyryan, @LizCarolan
You can get this kind of targeting through geo, or in some places through medical data brokers. It's possible that all Twitter got was an opaque audience segment. (Which makes none of this OK, but they might not be the targeting culprit.)
Replying to @jyasskin and @tobie, @othermaciej, @annevk, @infrastandard
Back when I was young, crazy, and innocent I remember that there was an OMA task force dedicated to defining what a mobile device is. It was three years in with no consensus.
If they’re not all dead they’re probably still at it.
Replying to @lukemulks and @johnnyryan, @LizCarolan
Of course. But my broader concern here is that opaque segments are likely to grow in popularity as tracking unravels, yet the first party has no ability to govern them nor users to evade them other than with one-off email addresses or the such.
I've been wondering what kind of traceability standard one could attach to segments such that some form of verification would be possible. I can think of legal mechanisms but nothing technical.
This is an amazing piece by @mariafarrell. The parallel between emotional labour and attentional labour struck me as particularly but the entire piece is worthy of your time, *especially* if you think it unlikely to be a good lens on the issue.
The one thing I would add is that I think this ties into the dearth of innovation we are going through in tech. Power imbalances lead to static social orders, which in turn are naturally hostile to innovation.
Sure enough we keep getting shiny gadgets, but what really is new? It's all innovation theatre.
Even the blockchain is 10 years old. Mobile 20, the Web 30, the Internet 50.
We're stuck because almost everything new coming out of tech is a stream of user-less products designed for no purpose other than to maintain the imbalance while tricking users into thinking they're in a great relationship.
Not to mention pervasive user-blaming under the so-called privacy paradox, well beyond phones. "They say they want privacy but they keep coming back. Stupid users are asking for it!"
Also, I'm not sure that this is the best metric. Several people I know who've recently joined Google have told me "sure, they're evil, but I might as well get some of the money before they get knocked back to size."
I’m not claiming it’s in any way a representative sample :) It’s almost certain that the people I hang out with are more aware of Google’s problematic practices around antitrust, privacy, publishers, radicalisation, etc.
Yes, I completely believe that most people at Google don’t realise just how destructive a force it is. People already there seem content to make the trains run on time and the problems are “not their area.” This is what I’ve heard from recent joiners.
The privacy issue is that the data was inappropriately acquired in the first place. That it is then well protected would be necessary to claim good privacy practices, but is not sufficient.
How did I misinterpret it? I am not pointing fingers or blaming anyone, just observing that people inside Google seem to be less aware of Google-caused issues than those on the outside. I’m not sure what I’ve said to irk you?
Happy to agree to disagree! Your description leads me to a question though (if you don't mind). You seem to describe a system of strong internal accountability, through transparency, docs, etc.
So when research like twitter.com/Miles_Brundage… is published (not a curve ball, literally just something I have in a tab) I presume you can look at some internal docs that eg. disprove the research or outline a plan to fix the issue?
My question is: if I indeed correctly understood the accountability that grounds your trust, how do you explain that the public-facing response on this topic is so poor (basically "the algorithm did it")?
People often seem to think that the independence of our news and opinion from the interests of the business is just something we say.
But here you have our friends from @nytopinion deliberately getting someone on our high-traffic site to tell we could suck less at privacy.
I know the feeling! But thankfully I don't need to convince my bosses, our questions aren't about "should we do this?" but rather "how do we make it work?" It's hard, I can't promise details or deadlines, but we're on it.
It's why this matters: "the old model of a independently managed and free press is being replaced by one where giant technology companies control user data and the purse strings."
Some people don't include this in their privacy threat model. That's a problem.
I'd love to! I'd be really interested in frank feedback about what we're thinking and working towards. And I can probably hop over to CMU easily. My DMs are open if you want to hash out details!
Replying to @othermaciej and @BrendanEich, @DSepDC, @jason_kint, @ashk4n, @johnwilander, @JustinBrookman, @johnnyryan, @dmarti, @pdolanjski
Yeah, I don't think publishers would be interested either. I appreciate the willingness to look for alternatives, though, and we certainly have ideas for accountability to contribute.
Replying to @hibaymj and @awwscript, @RubenVerborgh
In fact, people have died from the effects of radicalisation, harassment, etc.
No one is saying that you can foresee every malicious use, the baddies are creative for sure. But not trying is negligent, in some cases criminally negligent.
Replying to @awwscript and @hibaymj, @RubenVerborgh
Superhuman is a clear-cut case. It’s not “tracking” in the generalised surveillance sense, it’s allowing one specific person to monitor the behaviour — including location — of a specific other person. It’s spyware. Thinking about misuse for one minute is enough, it’s not hard.
Replying to @awwscript and @hibaymj, @RubenVerborgh
Saying “we didn’t consider malicious actors” is very precisely like saying “we didn’t think about making this product safe”.
Someone who said that for a physical product would — rightly — get their asses kicked for it.
Replying to @awwscript and @benlikestocode, @hibaymj, @RubenVerborgh
It sometimes takes several people to screw up. But they didn't just embed an image, they built a service to enable people to know exactly when and where an email was opened.
Replying to @awwscript and @hibaymj, @RubenVerborgh
I have no idea why you're interested in shifting blame around nor why you think that digital products have no obligation to be safe, but unless you have a clear argument I'd kindly suggest we leave it at that.
Replying to @TomEtty and @ohunt, @Google, @nytimes
Thanks. The hard part though is not so much allies in the sense of supporting that direction, it's finding people who can figure out how to make alternatives work. We'll get there, but it's a tricky path.
Replying to @TomEtty and @ohunt, @Google, @nytimes, @decorrespondent, @The_Corres
Yes, I'm aware of this and I'm glad that it's being explored as an option (also eg. by @team_markup). It's not clear (yet) how to extend that to a massive newsroom with dozens of bureaus, correspondents, etc.
All of Gaul is divided into three. There are those who use butter, but also those who use olive oil or duck fat. But @can is right that the butter ones will outbutter Americans.
For sugar though the US is the worst by far.
That’s not how consensus works. It would be a veto if unanimity were required. Google’s formal objection requires a Director decision, but it’s in no way a veto. No member has veto power.
Replying to @GerritD and @PrivacyProject, @technology
Yes, I read the story and it calls it “an effective veto” and mentions consensus as the reason for that. It’s a good story, and I’m happy and thankful to see it because standards aren’t covered anywhere near enough, but this characterisation is inaccurate.
Replying to @GerritD and @PrivacyProject, @technology
A formal objection (FO in the lingo) is an escalation, not a veto. It is meant to be a continuation of the consensus process in that it is expected to suggest changes that would lead to its resolution by bringing dissent to the Director for consideration.
Replying to @GerritD and @PrivacyProject, @technology
The distinction matters because the goal of the consensus process is to produce the outcome with the least objections; and in this case the converse decision might lead to more FOs than we are seeing here. If these were vetoes it’d all be stuck.
Replying to @GerritD and @PrivacyProject, @technology
To wrap up: I’m sorry for being pedantic at you, I know that standards are weird, and again I’m very thankful that you’re covering this. On the off chance that you’re crazy enough to want to cover them more, I think that understanding these bizarre subtleties can help :-)
Replying to @GerritD and @PrivacyProject, @technology
Yeah — be mindful that it’s a bit like Interstellar in reverse though: what is experienced as two months on the outside is really just a couple of days in the standards world ;-)
Hear me out: what if we put all Android apps in some kind of centralised “app store”, that way there would be one single entity in charge and they would have the power to enforce policies to protect users?
I certainly agree it shouldn’t be tick-the-box, I was just making this joke because in DG it often feels like we’re always making stuff up as things happen because so much is relatively novel ground. “On the fly” is often hard to avoid.
I think that someone who has experiences threads in social networking is very, very unlikely to recognise the notion when they look at a hypermail archive page :-D I mean: lists.w3.org/Archives/Publi…
I mean, if anything, it’s unfair to @cwilso for anyone to think that his blog might look like that.
Frankly, I’m not even sure what product familiar to normal users I would compare this to to make them understand what it is…
(I’m not saying this to annoy you — mailing lists and archives are something the W3C could really do something about if we hope to have any manner of accurate reporting into this…)
I don’t disagree, but I think that in general we have to acknowledge just how insanely fucking hard it is to report on standards. You’re 100% right that it’s not a blog, but I spoke to the guy and he clearly put in a lot of homework to figure this story out.
I reached out to explain that this isn’t a veto — and it’s clear that he really tried to understand the Process, which I can only feel sorry he had to… Indeed it’s not a blog, but I’d cut him some slack :)
Replying to @wbm312 and @joejerome, @caprivacyorg, @PrivacyPros
One alternative would be to produce privacy regulation through a consensus-based open standards process which would then be bound into law. The downsides are that it would be slow, and it would require tough leadership to protect it from bad faith participants.
I was going to say the same. At this point I'm increasingly surprised that the Internet doesn't spontaneously disintegrate. Clearly computers are held together by a supernatural force; the jury is still out on how benevolent, or in fact sane, that force is.
J’ai parfois l’impression que la fonction première des intellectuels français est d’obscurcir le débat en étalant le maximum de spéculation sur un sujet dont ils sont studieusement ignorants.
This small detail is interesting: what is Netflix paying to get your viewing data when you’re watching TV _outside_ Netflix, and what do they do with it?
Outstanding thread about how your TV tracks your behaviour. I’m surprised that Pi-Hole isn’t more effective, I need to dig in to see if it details why.
This is essentially a solved problem, but between those who think Word is good enough, those who feel LaTeX is proof of some intellectual ability, and editors who believe their own citation format is the cornerstone of civilisation nothing can change.
It's true though, in some fields it's basically a shibboleth. As if using a poorly designed markup language to generate dated typesetting were a good in-group factor...
This is an issue I struggle with repeatedly as well. I've been in tech almost 25 years, I know a lot of outstanding people — people with *local* moral excellence. But some (I feel) support morally dubious behaviour at a higher organisational scale.
What can we do about this?
My basic contention is that "governance is ethics at scale". Not in the sense of having an organisation virtuous in the same way that an individual is, but rather following the view that we can build structures that enable global moral excellence (from varied local excellence).
That might sound cool (to me, at least ;) but how do you go about this? The details are complex but one simple notion is tying local action to global and nth-degree outcomes, with a focus on adversarial thinking to help avoid motivated reasoning and "unintended" consequences.
Classique. La question c’est est-ce que vous vous en seriez rendus compte si ça avait été un taux de réussite moins suspect (ex. pour cause de dates se chevauchant un peu)?
Oui oui, c’est un problème qui n’est pas surprenant, j’étais surtout curieux de savoir ce que vous aviez comme approche pour détecter ce type de problème. Un modèle qui marche à 100% tu sais qu’il te ment.